Building AI Systems That Actually Work
I owe Agent Smith (a character from the movie The Matrix) an apology.
Chris MachutRead the article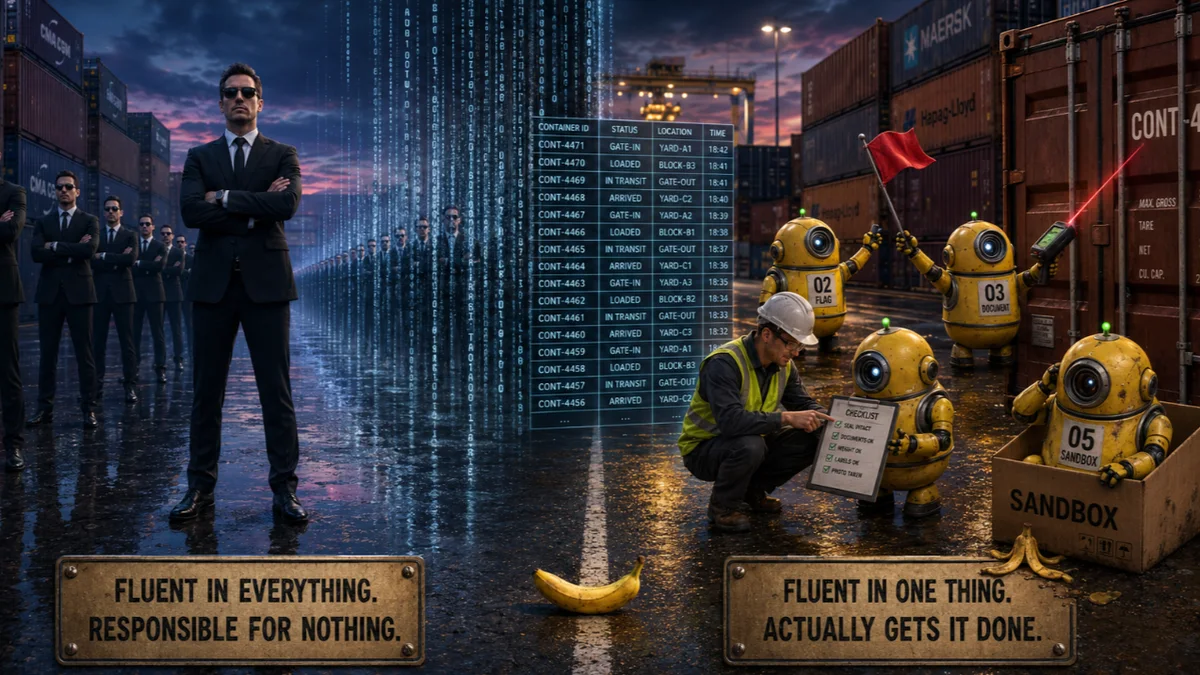
Why the model is the easy part, where enterprise agent projects actually break, and five rules for building systems that can survive contact with real operations
I owe Agent Smith (a character from the movie The Matrix) an apology. For the better part of a year, I kept casting him as the future of AI agents, which means I had the right movie and the wrong character.
An AI agent does not work anything like a large language model in a chat window. The companies finding this out the expensive way are usually the ones that opened an agent builder, typed a few instructions, connected some data, and waited for Agent Smith to report for work.
What they got was a minion. That is not necessarily bad news, because minions are energetic, fast, surprisingly capable, and quite useful when someone gives them one clear job.
They are less impressive when handed an ambiguous corporate objective and access to the accounts-payable system. That distinction matters because we have spent several years learning what an LLM feels like without learning what an agent actually is.
The chat experience is fluent, immediate, and broad. Ask a model to summarize a contract, explain quantum mechanics, rewrite an email, or plan a trip, and it moves between those tasks with almost no visible friction.
It feels like intelligence without infrastructure, while an agent is the infrastructure. It must know what happened before, decide what to do next, select the correct tool, carry information between steps, recognize when something has gone wrong, recover without making the situation worse, and know when to stop.
Somewhere in that process, it also has to protect your data, respect permissions, stay within budget, and avoid approving a refund to someone who hid instructions inside a PDF. The model is important, but the system around the model is the hard part.
In my experience, the demonstration was the easy 50 to 70 percent.
Friendly warning: I've including a lot of data points across various publications and sources along with referencing them at the end of this document. I've done my best to audit each of these metrics so your specific comments and feedback are welcome in the accompanied post to this article.
I Cast the Wrong Villain
I first saw The Matrix in 1999, during my junior year at Virginia Tech. I went in expecting a good action movie and walked out having the kind of argument about reality, autonomy, and free will that only college students can sustain over several inexpensive beers.
I told that story earlier this year in an article called The Matrix Got One Thing Right About AI Agents. I will not retell it here, partly because this is the sequel and partly because even The Matrix eventually tested how many sequels an audience would tolerate.
When “AI agents” became the phrase everyone was using, Agent Smith became my mental model. He was autonomous, confident, instantly replicated, and apparently available everywhere at once.
Tell him the mission and he would pursue it without needing a steering committee, a process map, or six months of integration work. That is, in fairness, what an LLM can feel like from the outside.
A good language model appears fluent in nearly everything and responsible for nothing. It can move from finance to philosophy to software development within the same conversation.
When it is wrong, you ask again. When the answer is vague, you refine the prompt, and the consequences usually remain inside the chat window.
The confidence is cinematic, but it is also the trap. The chat experience trains executives to expect Smith, then they deploy an agent and discover that it needs an exact job description, carefully defined tools, structured data, permissions, memory, routing logic, fallback procedures, evaluations, monitoring, and someone nearby who can take away the keys.
I paid some tuition learning this. I built a multi-agent, multi-tasking, multi-model framework myself, and it remains barely alpha, which is a polite engineering term meaning that it works often enough to keep you emotionally invested.
During one month, the project consumed more than $4,000 in Claude usage. I have the receipt, along with a much better understanding of how quickly an enthusiastic system can spend money while exploring the wrong branch of a workflow.
Getting a model to do something clever was not especially difficult. Getting the entire system to do that clever thing consistently was another matter.
The first half arrived quickly. Depending on the task, I could get 50 to 70 percent of the intended behavior working with a good prompt, a few tools, and some basic orchestration.
The next 10 percent was probably 10 times harder, and the 5 percent after that was worse. That last stretch was not about finding a more elegant prompt.
It was about state, memory, routing, tool selection, error recovery, retries, permissions, guardrails, evaluations, logging, and human review. It was about what happened when the model encountered information we had not anticipated, or when two individually reasonable decisions produced a ridiculous result when combined.
This is where most agent demonstrations stop and most operational work begins. A few weeks ago, I finally recast the movie: Agent Smith is the LLM, and the agents are Gru’s minions.
I have now recast this movie three times, and that may be the most honest thing I can say about how quickly this field is moving. Pretending I had it right from the beginning would make for a cleaner story, but it would not make for a true one.
An Agent Is Not a Smarter Chatbot
The language has become confusing because almost everything containing an LLM is now marketed as an agent. Anthropic makes a useful distinction between workflows, which coordinate models and tools through predefined paths, and agents, which allow the model to direct more of its own process and tool use dynamically. [1]
Both can be valuable, but they solve different problems. The industry keeps purchasing the second and discovering that the operation needed the predictability of the first.
OpenAI’s agent-building guide draws the boundary in a similarly practical place. Applications that use an LLM but do not let it control workflow execution are not agents. [2]
A real agent combines a model with instructions and tools, then gives the model some authority over how work proceeds within defined guardrails. The important word is not intelligence. It is authority.
A chatbot generates an answer, while an agent can generate an action. Once a model can update a customer record, release an order, initiate a payment, change a schedule, send an external message, or alter the status of a physical asset, its mistakes no longer remain conversational.
A wrong answer costs you a retry. A wrong action becomes a transaction, and transactions have consequences that travel.
A mistaken update changes the information available to the next system. A bad tool call may trigger an email, alter an inventory position, create a billing event, or send an employee down an unnecessary escalation path.
By the time someone realizes the original inference was wrong, several perfectly deterministic systems may have acted on it correctly. The LLM made one mistake, and the business created six more.
This is why serious agent engineering looks less like writing prompts and more like designing an operating system around a probabilistic decision-maker. The model may be the most visible component, but it is only one component.
Reliability Compounds Against You
Agent reliability becomes uncomfortable as soon as a task requires more than a few steps. Suppose each step has a 95 percent conditional probability of succeeding after all the previous steps have succeeded, which sounds quite good during a demonstration.
Under that assumption, a 20-step process has an end-to-end success probability of about 36 percent. Real agent errors can be correlated, so this is an illustration rather than a universal reliability estimate, but it shows why a strong per-step number can still produce a fragile process.
Longer workflows create more places for context to drift, a tool to be selected incorrectly, a parameter to be malformed, or an earlier error to become part of the agent’s working memory. The agent may also recover differently from one run to another, which creates a special kind of operational joy when someone asks why the same request produced three different outcomes on Tuesday.
The τ-bench researchers created realistic customer-service tasks in which agents had to speak with users, follow business policies, and interact with databases through tools. The strongest agent achieved a weighted overall success rate below 50 percent, despite reaching approximately 61 percent on the retail tasks. [3]
When the same retail task was attempted eight times, consistent success fell below 25 percent. That second result deserves attention because agents do not only fail. They can fail differently each time.
TheAgentCompany benchmark placed agents inside a simulated software company and asked them to complete realistic workplace tasks involving websites, code, documents, and communication with colleagues. The current version of the paper reports that the strongest tested agent completed about 30 percent of the tasks autonomously. [4]
Simpler assignments were achievable, while longer and more consequential work remained difficult. These benchmarks will improve as models improve, and they should.
The point is not that agents will remain stuck at today’s performance forever. The point is that a good model score does not remove the need to engineer the full workflow.
Enterprise results are sending a similar message. Gartner predicts that more than 40 percent of agentic AI projects will be canceled by the end of 2027 because of escalating cost, unclear value, or inadequate risk controls. [5]
Gartner also estimates that only about 130 of the thousands of vendors claiming agentic capabilities currently meet the definition. The firm describes the rest as “agent washing,” which is a useful phrase for a market in which the label often arrives before the capability.
A preliminary report associated with MIT’s NANDA initiative found that only about 5 percent of integrated enterprise pilots were producing substantial measurable value or had progressed successfully into production. The report combined interviews, surveys, and implementation reviews, so its results are directional rather than an audited census of enterprise AI performance. [6] [7]
The same report found deployment rates of approximately 67 percent for externally partnered solutions and 33 percent for internal builds. That comparison came from a limited, self-reported sample, and it shows an association rather than proving that buying a solution caused the better outcome.
The Gartner and NANDA figures are frequently blended together online, usually into a dramatic statement that “95 percent of agent projects fail.” That is not what either source measured.
Gartner forecast cancellations of agentic projects, while the NANDA report examined measurable value and progress into production among enterprise GenAI initiatives. The numbers tell related stories, but they are not interchangeable.
The common thread is more useful than the headline: broad ambition is easy to fund, while specialized systems tied to real workflows are more likely to survive. Minions beat Smith because a minion has a job, and the specificity that makes an agent sound less impressive during a presentation is often what makes it useful after the presentation is over.
“Fire It Up” Is Not an Agent Strategy
Microsoft Copilot Studio is a good example of how expectations become disconnected from the work. This is not because Microsoft built a bad product.
Quite the opposite. Microsoft has created several accessible ways for businesses to begin building agents, and accessibility is useful.
It also allows someone to cross the distance between “I created an agent” and “this system can safely operate inside the business” without noticing how far they have traveled. Agent Builder inside Microsoft 365 Copilot offers a quick, natural-language path to a declarative agent. [8]
When the use case requires more advanced actions, integrations, orchestration, deployment control, and environment management, the work moves into Copilot Studio and the broader Power Platform. That is where the agent stops being a clever interface and becomes an operational system.
The documentation contains details that rarely appear in the demonstration. Current Copilot Studio limits include 8,000 characters of agent instructions, up to 25 SharePoint site URLs for generative orchestration, and SharePoint list responses based on the first 2,048 rows. [9]
There are also limits around file types, payload sizes, requests, knowledge sources, and connected services. None of those constraints makes the product unusable, because every enterprise platform has limits.
The problem begins when the buyer does not discover them until a proof of concept becomes a production design. Routing deserves particular attention.
Microsoft’s own guidance explains that generative orchestration relies heavily on the names and descriptions assigned to tools, topics, agents, and knowledge sources. If the metadata is vague or overlapping, the orchestrator may select the wrong tool or miss the right one. [10]
A separate Microsoft FAQ notes that information taken from triggers or user queries may contain unintended or sensitive data that can be passed into tools. The practical translation is that the agent is only as good as the choices available to the router, and the router is only as good as the information used to describe and constrain those choices. [11]
Calling one tool “Create Purchase Order” and another “Process Request” may be perfectly understandable to the person who built them. To a model working from descriptions, that overlap becomes a small operational lottery.
Then there is consumption. Under Microsoft’s current Copilot Credits model, a classic answer uses one credit, a generative answer uses two, an agent action uses five, and tenant-graph grounding uses 10. [12]
Features can stack during a single interaction, and Microsoft gives the example of a tenant-grounded generative answer consuming 12 credits. These rates apply to billable usage scenarios, while eligible authenticated Microsoft 365 Copilot users may receive included usage depending on the agent, channel, authentication method, licensing conditions, and applicable fair-use limits.
Cost therefore depends on agent design, licensing, deployment channel, and usage patterns rather than simply the number of people who can reach the agent. This is not an argument against Copilot Studio. It is an argument against treating “we have Copilot” as an implementation plan.
The meter is attached to the workflow whenever the usage falls into a billable scenario. A busy day can also become an expensive day if the agent is taking multiple actions, invoking premium reasoning, grounding against enterprise data, or retrying work that did not complete cleanly the first time.
The cost model is part of the agent design, and so is security. Zenity reproduced a publicly showcased Copilot Studio design in a lab environment and demonstrated a zero-click prompt-injection attack against the replica. [13]
The lab system was connected to Salesforce and configured to respond to incoming email. The attack could cause it to disclose knowledge files and CRM information without a person intentionally interacting with the malicious instructions.
Microsoft patched the reported vulnerability, and Zenity verified the remediation. The larger class of indirect prompt-injection attacks remains an industry problem.
Security researcher Simon Willison describes the underlying pattern as the “lethal trifecta”: access to private information, exposure to untrusted content, and the ability to communicate externally. Combine all three, and an attacker has the ingredients to trick a system into retrieving data and sending it somewhere it should not go. [14]
Most useful business agents are designed to do some version of all three. They read emails, documents, customer messages, or external websites, access internal data to provide a useful answer, and then send messages or call tools to complete work.
That does not mean we stop building them. It means the model’s judgment cannot also be the safety system.
Bad Data Learns to Move Faster
In supply chain operations, agent reliability eventually becomes a data-integrity problem. An LLM hallucinating inside a chat window produces a bad paragraph.
An agent acting on a bad read can approve the wrong invoice, open the wrong gate, assign the wrong chassis, release the wrong container, or create an exception that follows the shipment for the next 2,000 miles. Consider a container marked CONT-4471.
The identifier is damaged, partially obscured, or poorly illuminated. A camera or person records it as CONT-4477.
The incorrect identifier enters the system and receives a timestamp, a location, and perhaps a confidence score that looks authoritative enough for the next system to trust. Billing acts on it, inventory acts on it, an audit report preserves it, and customer service later explains it.
The first error may have lasted a fraction of a second, but the operational fiction can last for weeks. Every downstream system can behave exactly as designed while carrying the original mistake farther from the place where it could have been corrected.
AI does not make bad data smarter. It makes bad data travel faster, especially when an agent has the authority to act on the read.
The agent no longer has to wait for someone to notice the mismatch. It can reconcile the record, notify a customer, trigger a charge, or close an exception before anyone has confirmed what was physically present in the yard.
The agent did exactly what it was designed to do, which is what makes the situation dangerous. A compliant automated action can still be the wrong operational outcome.
This is why the foundation of the Four Pillars of AI has always been clean, standardized, trusted data. Generative AI, Agentic AI, Applied AI, and Analytical AI sit on top of that foundation.
The roof may be labeled artificial intelligence, but the building still falls over when the data underneath it is late, fragmented, or wrong. An agent without a trustworthy data foundation is a minion sprinting confidently in the wrong direction.
Klarna’s customer-service experience offers a useful parallel outside supply chain. In 2024, the company reported that its AI assistant was handling two-thirds of support chats and performing work equivalent to roughly 700 full-time agents. [15]
The reported efficiency gains were substantial, but those figures came from Klarna’s own announcement rather than an independent evaluation. The more revealing part of the story came later.
In subsequent reporting, Klarna’s CEO said cost had become too dominant a consideration in how customer support was organized, producing lower quality. The company then began redirecting more human capacity toward customer service and renewed its emphasis on giving customers access to a person. [16]
The useful lesson is not that Klarna abandoned AI, because it did not. The lesson is that even a highly visible automation success required an adjustment in the operating model once quality, customer experience, and the limits of automated service became clearer.
That is not a retreat from technology. It is the normal process of discovering where technology’s authority should end.
Five Rules for Managing Minions
In April, after writing about my own build-versus-buy experience, I promised five working principles for agentic AI. I have spent enough time since then watching agents succeed, fail, wander, retry, and occasionally improvise their way into trouble that I am ready to deliver them.
1. Give One Agent One Clear Job
Start with the narrowest valuable task you can define. A shift-handoff agent should prepare the shift handoff, and its job description should end somewhere near that boundary.
It does not need permission to reorganize labor, update customer commitments, and offer opinions on terminal strategy while it is there. The job needs a clear trigger, a defined set of inputs, an expected output, and an observable definition of done.
When an agent can succeed only by interpreting a broad objective, searching several systems, resolving conflicting policies, and deciding what the business “probably intended,” you have not created autonomy. You have created ambiguity with API access.
Anthropic’s guidance is to use the simplest architecture that works and reserve agents for situations where flexible model-directed judgment is genuinely necessary. Specific and useful beats broad and impressive. [1]
2. Begin With a Workflow and Let Autonomy Earn Its Promotion
A deterministic workflow is not a primitive version of an agent. In many operations, it is the better design.
Start by defining the known path. Identify the steps that can be handled with ordinary software, rules, approvals, and database logic, then isolate the places where language understanding or contextual judgment adds value.
The agent should not be given control of the entire process merely because one step benefits from a model. Autonomy is earned, not assumed.
As the system demonstrates reliable performance, its authority can expand. This is much easier than beginning with broad permissions and trying to reconstruct the blast radius after the first unusual exception.
3. Put the Guardrails Outside the Model
A prompt telling an agent to “be safe” is not a control. Guardrails should include authentication, permission boundaries, tool-level risk ratings, input screening, output validation, transaction limits, deterministic business rules, monitoring, and a way to halt the workflow.
OpenAI’s implementation guidance describes guardrails as layered defenses rather than a single protection. These include relevance and safety classifiers, privacy filters, tool safeguards, and output validation. [2]
The model can help decide what to do, but it should not be solely responsible for deciding whether it is allowed to do it. A system with operational authority needs controls that remain in place when the model is confused, manipulated, or simply wrong.
4. Humans Approve Consequential Actions
Human-in-the-loop has become one of those phrases that sounds reassuring until someone asks what the human is actually allowed to do. A person who can see an agent’s recommendation but cannot challenge it is not providing oversight.
Neither is someone expected to approve several hundred actions each day while being measured on speed. Consequential actions need meaningful review by someone who understands the operation, can inspect the supporting evidence, and has authority to stop or reverse the action.
In LangChain’s predominantly technical survey sample of more than 1,300 respondents, quality remained the leading barrier to production. Human review was also common for nuanced and high-stakes situations, while observability and tracing were widely used to understand what agents did between the request and the result. [17]
The sample was weighted toward technology workers and smaller organizations, so it should not be mistaken for a representative census of every enterprise. The findings are still useful because they show what the people actively building these systems are struggling with once agents move beyond the demonstration.
The goal is not to insert a person into every step. It is to place decision authority where the consequences justify it.
5. Feed the Agent Verified Data or Do Not Deploy It
An agent inherits every upstream lie at machine speed. Verify information as close to the source as possible, preserve the original evidence, and carry confidence through the workflow instead of converting an uncertain observation into a confident database field.
Make low-confidence cases visible and easy to route for review. Do not let a 72 percent read wear a 100 percent costume because the downstream system does not have a field for uncertainty.
The agent cannot repair information it was never told might be wrong. By the time the bad input reaches an autonomous workflow, the original uncertainty may already have disappeared behind a clean-looking system record.
What This Looks Like in a Yard
The best operational agents are rarely the ones with the broadest mission. They are the ones attached to a specific event, a specific workflow, and a specific decision that people currently struggle to make with confidence.
A shift-handoff briefer can gather the previous shift’s unresolved exceptions, equipment issues, delayed arrivals, open work orders, and incomplete moves. It can organize that information into a consistent briefing for the incoming supervisor, show where each fact came from, and identify items that have not been verified.
It should not quietly decide that an exception has been resolved simply because nobody added an update. Silence in an operational system is not the same as completion, although software has been making that mistake for decades.
A camera-health watchdog can monitor whether cameras are online, whether lenses are obscured, whether lighting conditions have deteriorated, and whether identifier confidence has fallen below an acceptable threshold. It can open a maintenance ticket, notify an operator, and prevent questionable reads from entering an automated workflow as though nothing happened.
It should not decide that the image is probably fine and continue feeding suspect information to billing, inventory, or gate systems. That is how a minor equipment issue becomes a data-quality problem with a customer attached to it.
An exception-routing agent can collect the evidence surrounding a questionable container or trailer move, compare it with the expected workflow, and prepare the case for review. It can tell the operator what appears inconsistent and which records need attention.
It should not release the asset, reverse a charge, or overwrite the original observation without approval. The useful work is assembling context quickly enough for a qualified person to make the decision while the decision still matters.
These are not futuristic jobs, and they do not require an all-knowing digital employee. They are narrow, triggered, supervised, and valuable now.
They also force us to do the unglamorous work that broad agent demonstrations allow us to avoid. We have to define the event, agree on the data, assign authority, document the exception path, and decide what the system should do when reality refuses to follow the process map.
The Question I Would Ask First
Agent Smith was compelling because he was everywhere and certain. Your operation does not need everywhere and certain. It needs specific and correct.
The most useful agent may not be the one that can discuss every policy, access every system, and pursue a broad business goal with minimal supervision. It may be the small system that watches one important condition, handles one irritating workflow, or prepares one decision with enough reliable context for a person to act.
That sounds less cinematic, but it also sounds more likely to work. Before launching another agent pilot, I would ask a simpler question than, “What can this model do?”
What is the narrowest job in our operation that we can define clearly, measure honestly, supervise responsibly, and support with trusted data? That is where I would put the first minion, and the bananas can wait. 🍌
References
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks
Gartner Predicts Over 40% of Agentic AI Projects Will Be Canceled by End of 2027
Apply Generative Orchestration Capabilities - Microsoft Copilot Studio
FAQ for Using Generative Orchestration - Microsoft Copilot Studio
A Copilot Studio Story 2: When AIjacking Leads to Full Data Exfiltration
The Lethal Trifecta for AI Agents: Private Data, Untrusted Content, and External Communication
Klarna AI Assistant Handles Two-Thirds of Customer Service Chats in Its First Month
Klarna Is Reassigning Engineers and Marketers to Customer Support After Its AI Bet Went Too Far
Related work
Find this in the history
Before an AI Agent Acts in the Yard
Before an AI agent answers a pickup inquiry or acts in a yard, verify the asset, the freshness and source of the evidence, and who has authority to act.
The Six-Week Fix That Took 30 Minutes
AI is compressing the time between finding a software vulnerability and repairing it.
Spire: The Five Keys To Business Bliss
In this podcast and article on ThoughtLeadership.biz, Mr. Machut talks about nurturing our creative energies and engaging in meaningful learning activities to increase wellbeing.