What Authority Has Your AI Earned?
During the Supply Chain AI Hot Seat at Intermodal Association of North America EXPO 2026, I was making what I thought was a technology argument.
Chris MachutRead the article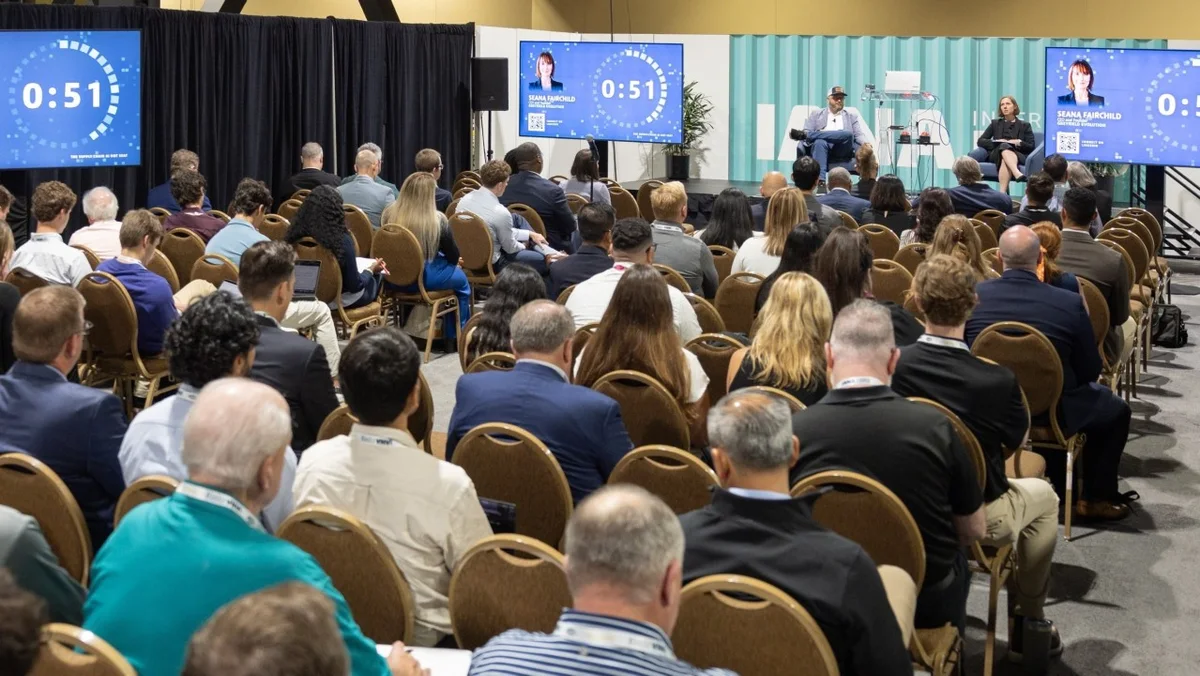
During the Supply Chain AI Hot Seat at Intermodal Association of North America EXPO 2026, I was making what I thought was a technology argument. Seana Fairchild and I were debating why AI projects fail, and I was describing the difference between a process map and the work itself. The map showed a truck arriving, a container moving and a customer getting an update. In the operation I asked the audience to picture, the appointment was wrong and the container number was damaged. People kept the work moving through phone calls and spreadsheet updates that the diagram never accounted for.
When Seana got her turn, she pointed out that I had just made her argument for her. “Did any of you hear a tech perspective in that at all?” she asked. She had a point. I had been explaining what the technology was missing by describing the people who understood the operation well enough to keep it working.
That exchange sharpened a question I raised later in the session:
What authority has AI earned?
I wanted evidence that a container moved before software started making decisions about it. Seana wanted us to establish who was allowed to make those decisions and who was accountable when something went wrong. As we worked through the examples, it became difficult to treat those as separate concerns. Giving AI more responsibility should depend on whether the whole arrangement works, including the people expected to catch its mistakes.
When your systems disagree at the gate
Put yourself at the gate in that example. A driver has arrived to collect a container, but the gate record and the yard system disagree about its status. Dispatch is working from another update. You have to decide what happens next while the driver waits, and you cannot resolve the problem simply by declaring one department responsible for the answer. An AI tool might collect those records and offer a recommendation. You still need to know which information deserves to be believed.
I would start by asking what physical event makes the status true. A camera observation could help establish that a particular container was present at a particular place and time. It would not, on its own, establish that every condition for releasing that container had been met. Even with a correct identification, the permitted next step depends on information and authority beyond the image.
An exception needs somewhere to go
Now suppose part of the identifier is obscured. You need the system to preserve that uncertainty and route it somewhere useful, perhaps to another observation or a person who can resolve the conflict. Otherwise, an ambiguous image could become a clean-looking record that someone downstream treats as fact. I would evaluate that exception path as seriously as the successful read, including whether the system recognizes when it needs help.
That last part deserves scrutiny. A high confidence score is not automatically a reliable probability of being right; research on neural-network calibration has demonstrated that gap. Forwarding low-confidence results to a person still leaves the incorrect results the system was confident about. I would want the evaluation to examine those, too, rather than measuring only the cases AI volunteers for review.
When an exception does reach a person, we have another part of the workflow to design. Seana warned about calling something human oversight when one person is expected to review thousands of records. In our gate example, the reviewer would need access to the conflicting evidence and enough time to investigate. They would also need clear authority to hold the transaction or escalate it, with a plan for what happens when nobody responds. A review queue does not help the waiting driver unless someone can actually work it.
The operator belongs in the design meeting
As you trace that decision through the operation, the person you need in the design meeting becomes fairly obvious. It is the operator who knows why the appointment record cannot always be taken at face value, or which update requires a phone call before anyone acts on it. Ask that person what they do when the system is wrong, and stay long enough to understand the answer. A workaround may be a bad habit worth removing. It may also be doing essential work your proposed automation has not accounted for.
"A workaround may be a bad habit worth removing. It may also be doing essential work your proposed automation has not accounted for."
That conversation becomes harder if the operator believes the purpose is to document their job so it can disappear. Those of us leading AI projects owe people a credible explanation of how their responsibilities will change, along with time to learn the new work. Their involvement should begin while the workflow is being designed, when their knowledge can still change what gets built. Asking for enthusiasm a few weeks before launch is a poor substitute.
At SiteTrax.io, we encouraged practical AI use from leadership and began applying it where it could improve actual work. Our team became able to accomplish substantially more, without laying anyone off as a consequence of that internal push. The additional capacity also gave us more work and more opportunities to pursue. That is our experience, rather than a promise about what happens to employment everywhere. It has also given me a reason to pay attention to what comes after a productivity gain: the organization still has to decide how much new work it can responsibly take on.
Start with one problem, but follow the whole workflow
I see this as a systems-engineering problem. In NASA’s framing, the system includes people and procedures alongside hardware and software, and its value depends on how those parts work together. Applied to our world, I take that to mean a faster task is only an improvement if the operation can use the result without creating a larger problem elsewhere. A quoting tool, a camera model or an exception handler can perform its assigned function well while the overall workflow still disappoints.
We can put that thinking to work without launching an enterprise-wide AI program. Suppose we begin with delays caused by conflicting container statuses at one facility. Before changing anything, we establish how long those cases take to resolve and how much operator time they consume. Working with the people handling them, we determine which conflicts could be settled with better observations and which depend on a business decision. The scope is narrow enough to test, but it follows the problem through to an operational outcome.
Give AI a bounded role, then complete the loop
During the debate, I referenced John Boyd’s OODA loop: observe, orient, decide and act. Boyd developed it as an action-and-feedback framework, which I would adapt here to the combined work of the AI, the operator and the organization. This is a way to keep testing our understanding of the operation, rather than treating deployment as the finish line. For our gate pilot, I would use it this way:
Observe. Check whether the observations identify the right asset and preserve when and where it was captured. Keep missing or conflicting evidence visible.
Orient. Compare those observations with the appointment and status records. Bring in the operator’s knowledge to understand what the disagreement actually means.
Decide. Let AI recommend a next step within defined limits, with a named person responsible for consequential decisions. Establish when the evidence is insufficient to proceed.
Act. Execute only the action that has been authorized. Creating an investigation task and releasing freight require separate permissions, even when they begin with the same record.
Then we return to observation and find out what happened. Did the conflict get resolved sooner? How much review effort and rework did it require? We would compare the results with our baseline, including the cost of operating the technology. If the alerts arrive faster but the driver waits just as long, we still have something to fix before calling the project a success.
"If the alerts arrive faster but the driver waits just as long, we still have something to fix before calling the project a success."
Once the pilot demonstrates that it saves investigation time while staying within agreed error limits, we have evidence for considering another permission. We might allow the system to create an internal task automatically instead of waiting for someone to approve that step. That would be a specific expansion of responsibility, not a general declaration that we now trust AI.
We should also be willing to take authority back. A changed workflow or deteriorating performance may justify returning an automated action to human review while we investigate. NIST’s AI Risk Management Framework Playbook explicitly provides for bypassing or deactivating systems when their performance no longer fits the intended use. I would want those conditions agreed before deployment, rather than negotiated during an incident.
Where we begin on Monday
None of this requires waiting for perfect data or mapping every possible exception across the company. We need sufficient evidence for the decision we are testing, with a workable response when that evidence is missing. We may also discover that a corrected handoff or conventional automation solves part of the problem more simply. I would count that as progress. The purpose is to improve the operation, and that should remain true even when the useful answer involves less AI than we expected.
Looking back at the debate, the moment that stays with me is Seana recognizing the people inside my technology argument. I still want better evidence before a system acts, but I also want the person who has been resolving the bad records involved in deciding what that system should be allowed to do.
For those of us building and buying AI, that is a good place to begin Monday’s conversation. Spend time beside the operator handling a troublesome pickup and follow the work through to resolution. We should be able to give AI a useful job somewhere in that process, then come back together to see whether the next pickup was easier to handle before assigning it more responsibility.
Related work
Find this in the history
Before an AI Agent Acts in the Yard
Before an AI agent answers a pickup inquiry or acts in a yard, verify the asset, the freshness and source of the evidence, and who has authority to act.
From Buzz to Blueprint: Two Years on the Road with the Four Pillars of AI
A field report from a dozen stages, four webinars, and a couple hundred honest poll responses on how the supply chain actually adopts AI.
Managing the AI Child
Chris Machut discusses treating AI like a learner: set clear expectations, define success and failure, and avoid promising more than the system can deliver.